SRHE Blog

The Society for Research into Higher Education


Leave a comment

When will the underrepresentation of Black professors end?

by Zarus Cenac

On the SRHE Blog, in May and July, I wrote about the underrepresentation of Black people amongst professors in the UK higher education sector. In response to my May blog post, a commentator brought up the idea of a time delay between “the demographics of academia” and “changes in the wider population”, and that “estimating what is a reasonable lag is challenging and probably highly contestable” (Golding, 2026, para. 1). The present blog post takes a step along that path. There is an underrepresentation of Black female professors and Black male professors (Paper Whispers, 2025; Figure 1) – for females and males separately, I estimate how many years it may take for the underrepresentation of Black professors to end (Figure 2). This is done by estimating when the percentage of professors who are Black will eventually match Black representation in part of the UK population who are around a certain age (Figure 2). I also look for an indication of whether underrepresentation has been tangibly improving for Black female professors and Black male professors (Figure 2). Additionally, I consider which is the better of two similar methods for calculating the percentage of professors who are Black (eg, Figure 4a and 4b).

Figure 1

The Underrepresentation of Black Female Professors and Black Male Professors in UK Higher Education Institutions
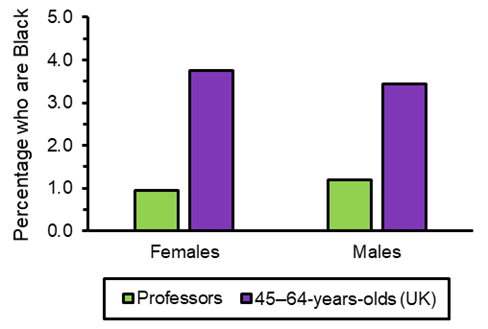
A bar chart is shown – for females, .95% of professors are Black and 3.75% of 45-to-64-year-olds are Black. As for males, Black people are 1.19% of professors and 3.44% of 45-to-64-year-olds.

Note. Data (2024–25 academic year) from Higher Education Statistics Agency (HESA, nd-a) and 2021/2022 UK Census data (Office for National Statistics, 2025) were used regarding Figure 1 and in analysis. As before, statistical analysis was used to explore the representation of Black professors – see Box 1 for a description of this analysis.

Black representation over time: Professors

There have been observations on what the representation of Black professors looks like at different points in time (eg, Gibney, 2024; Rollock, 2025). For instance, between the 2021–22 and 2022–23 academic years, there was a 0.2% increase in the percentage of professors who are Black, with the percentage being 0.9% in 2022–23 (Gibney, 2024), and the percentage of female professors who are Black was 0.6% in 2019–20 and 0.8% in 2022–23 (Rollock, 2025).

I used HESA data for the academic years 2014–15 to 2024–25 (HESA, nd-a) to calculate the percentage of professors who are Black amongst females and amongst males (the green circles in Figure 2). Based on representation across those academic years, predictions were made for Black representation in academic years after 2024–25 by fitting a (quadratic) trendline to the data for females and for males – the trendline is the green, dotted line in Figure 2. Despite trendlines predicting a continued increase in Black representation in the professoriate, it should be expected that the percentage will plateau at some point (see the plateauing indicated in Figure 3 regarding non-professors).

Figure 2

Predicting When Black Professors are no Longer Underrepresented
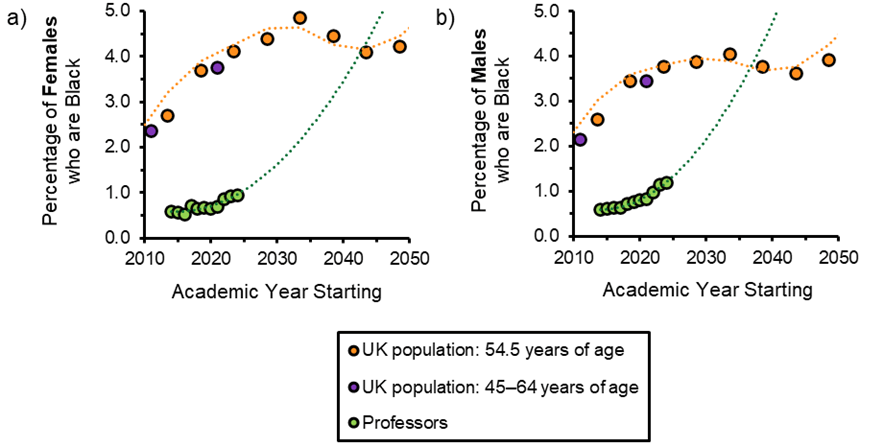
Scatter graphs showing the academic year when the representation of Black people amongst professors is predicted to match Black representation in 54.5-year-olds for females and males. That academic year is about 2043–44 and 2037–38 respectively for females and males.

Note. Underrepresentation is predicted to end in the academic year when dotted lines cross. HESA (nd-a) data and 2021/2022 UK Census data (Office for National Statistics, 2025) were used for Figures 2 and 4. HESA (nd-a) state the number of professors by ethnicity categories: Asian, Black, Mixed, Other, White, and unknown ethnicity. In Figure 2 (and Figure 1), the representation of Black professors was calculated only using persons of known ethnicity. Additionally, using Census data (Nomis, 2013; Office for National Statistics, 2025), for females and males, Black representation amongst 45-to-64-year-olds in the UK was i) estimated for 2011 and ii) calculated for 2021/2022 (Box 2). For simplicity, census year (Office for National Statistics, 2025) was treated as the year when the academic year starts, eg, with the 2021/2022 Census data treated as the 2021–22 academic year.

Black representation over time: 54.5-year-olds in the UK population

The representation of Black people is lower in the professoriate than amongst people in the UK population who are between 45 and 64 years old – an age range which should reflect the ethnic composition of the professoriate well enough (Cenac, 2026). The midpoint of this age range is 54.5 years of age. For females and males, UK Census data are available for various ages and age ranges, for example, 15 years old, 50-to-54 years old, and 65-to-69 years old (Office for National Statistics, 2025). I estimated the year when ages and age ranges are 54.5 years old. To estimate when an age range is 54.5 years old, I calculated the midpoint of the age range, for example, the midpoint for the 50-to-54 age range is 52 years – the midpoint was used to represent the entire age range.

For ages and age ranges, UK Census data (Office for National Statistics, 2025) were used to calculate the percentage of females and males in the UK population who are Black. Figure 2 shows those percentages and the year in which the age/midpoint is 54.5 years old (orange circles). To estimate/predict what Black representation is like amongst 54.5-year-olds in the UK population for females and males at various times, a moving average line was used – the line can be seen in Figure 2 as a line which is orange and dotted.

The estimated representation of Black people amongst 54.5-year-olds seems to be acceptable as a stand-in for Black representation in 45-to-64-year-olds in the UK in the recent past if we consider representation in 45-to-64-year-olds in 2021/2022 and estimated representation in 45-to-64-year-olds in 2011 (see Box 2).

Figure 3

Level of Black Representation in Non-Professors

Scatter graphs present the percentage representation of Black people amongst non-professors for females and males for the academic years 2014–15 to 2024–25. For females, percentage representation goes from 1.51% in 2014–15 to 3.61 in 2024–25. For males, Black people were 2.10% of non-professors in 2014–15, rising to 4.88% in 2023–24, and at 4.86% in 2024–25.

Note. Data (which are of academics who are not professors) are from HESA (nd-a), and percentage representation was calculated from non-professors whose ethnicity is known.

Predicting an end to underrepresentation

The ethnic diversity of the UK has been predicted to be higher in 2051 than it was in 2001 (Rees et al, 2011). So, it should not be surprising that Black representation amongst 45-to-64-year-olds seems to have been increasing (see the purple circles in Figure 2). Therefore, when examining whether the underrepresentation of Black professors is improving, it is important to take into consideration changes in representation within the UK population (Figure 2). For females and males, between the academic years 2014–15 and 2024–25, the increase in the representation of Black professors does not seem to outpace the estimated increase in the representation of Black people who are around 54.5-years-old (Figure 2). Therefore, between those academic years, there appears to have been no tangible improvement in the underrepresentation of Black female professors and Black male professors.

It is possible to estimate the academic year when there will no longer be an underrepresentation. This can be done by seeing the academic year when dotted lines for professors and 54.5-year-olds cross over each other. That academic year is approximately 2043–44 for Black female professors and approximately 2037–38 for Black male professors. So, in the 2026–27 academic year, we are an estimated 17 years away from underrepresentation disappearing for Black female professors, and an estimated 11 years away for Black male professors.

Gains in Black representation amongst female and male academics who are not professors (Figure 3) suggest that there is reason to be optimistic that Black representation in the professoriate will increase for females and males. However, if Black representation amongst female non-professors is plateauing (at around 3.6%), then the trend amongst female non-professors (Figure 3a) does not bode well for an end to the underrepresentation of Black female professors by the early-to-mid 2040s (Figure 2a).

The percentage of professors who are Black, and the prediction of when underrepresentation disappears, depends on which of two (slightly different) methods is used to calculate the percentage (Figures 2 and 4). Using HESA data, the percentage of professors who are Black is calculated by dividing the number of Black professors by some sort of total number (eg, Gibney, 2024), and the two methods differ in how this total is defined (Figures 2 and 4).

Method 1: Known ethnicity only. When calculating the percentage representation of an ethnic group, or ethnic groups, the percentage can be calculated just from individuals for whom ethnicity is known (eg, HESA, 2026a). So, in this method, people of unknown ethnicity are not included in the total when calculating the percentage of professors who are Black (eg, Gibney, 2022; Figure 2).

Method 2: Overall. From looking at HESA (nd-a, 2026a) data, there seem to have been times when the percentage of professors who are Black (eg, Essilfie-Quaye et al, 2025; Gibney, 2024), or the percentage of female professors who are Black (Rollock, 2025), was calculated from a total number which includes people whose ethnicity is unknown. Under that method, when a percentage is calculated, a Black person could be part of the Black category or part of the unknown ethnicity category.

Compared to Method 1, Method 2 leads to a slightly lower percentage of professors who are Black (Figure 4a and 4b; also see Le Roux, 2022), and predicts that underrepresentation disappears a little further into the future (Figures 2 and 4). As briefly covered in my second blog post, the percentage of professors who are Black may seem smaller (but not very much smaller) than it really is. Method 2 would lead to a slightly further underestimation than Method 1 (Figure 4a and 4b). So, Method 1 may be a somewhat better method than Method 2 for considering the percentage representation of Black professors (eg, see Le Roux, 2022) and for estimating when underrepresentation will end.

Figure 4

Different Methods of Calculating the Percentage of professors who are Black
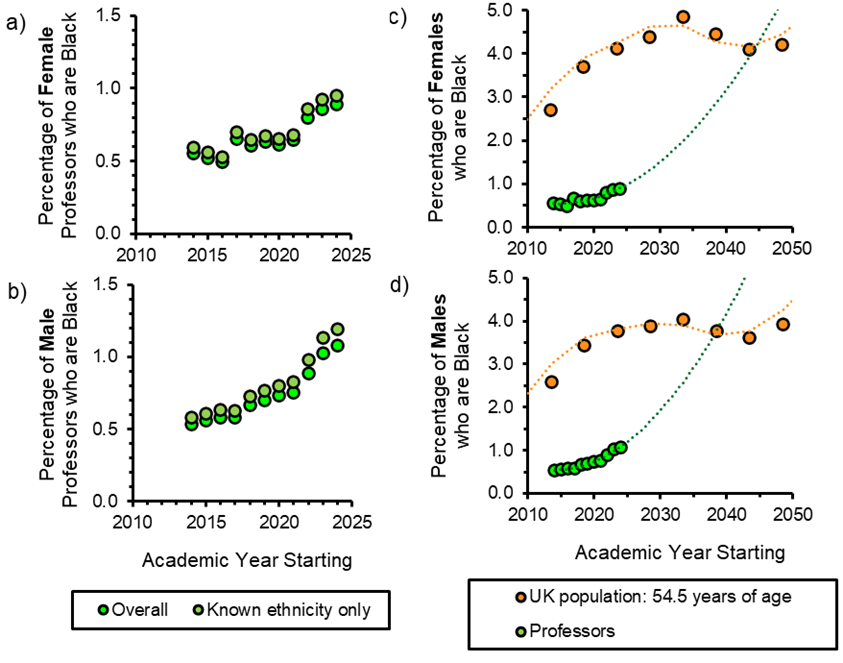
It is demonstrated, in scatter graphs, that Method 2 calculates a lower level of Black representation in the professoriate than Method 1 does for females and males. Other scatter graphs represent the prediction of the academic year when the underrepresentation of Black professors ceases, for females and males, under Method 2.

Note. For Figure 4c and 4d, analysis regarding Figure 2 was undertaken again, but without limiting analysis to professors of known ethnicity – it is predicted that Black professors will no longer be underrepresented by 2045–46 for females and 2038–39 for males. Considering data and literature (HESA, nd-a; Rollock, 2025), some of the percentages for Black female professors (overall) in Figure 4a are in Rollock (2025) to one decimal place.

Context and future research

There seems to be a dearth of literature which examines how percentage representation changes with time in academia and in the national population to see whether the extent of ethnic/racial underrepresentation in academia changes. So, it is hoped that the approach used in the present blog (Figure 2) is useful for exploring the underrepresentation of ethnic/racial groups in academia outside of Black professors. In previous research, a graph has shown 1) the number of geoscience PhDs gained by people in specific (underrepresented) ethnic/racial groups for various years (amongst the USA’s citizens or people with permanent residency in the country) and 2) the number of people in ethnic/racial groups in the USA for various years (Bernard & Cooperdock, 2018). The graph has been referred to when stating that, when considering four decades, “the representation of students from underrepresented minorities … has essentially been stagnant when compared with the proportion of the relevant groups in the US population” (Bernard & Cooperdock, 2018, pp. 292–293); the present blog post examines the percentage representation of Black people in the professoriate and in the UK population (Figure 2) – if not done so already, it may be useful to examine (across the years) the percentage representation of ethnic/racial groups in academia beyond the Black professoriate (eg, in achieving PhDs) alongside percentage representation at the national population level for an indication of whether ethnic/racial underrepresentation is changing and when the underrepresentation may stop.

In my first blog post, I described how a statistic known as Cohen’s h can quantify the extent that Black professors are underrepresented, and I considered how that statistic can be used to define when underrepresentation is no longer large enough to be noteworthy. Therefore, Cohen’s h could be used to estimate the academic year when the difference between Figure 2’s orange and green lines is no longer noteworthy – that year would likely be sooner than the year when underrepresentation is forecasted to stop.

Whilst this blog post predicts when underrepresentation will end for Black female professors and Black male professors (Figure 2), these predictions are not intended to be conclusive. Ideally, future census data (Northern Ireland Statistics and Research Agency, 2026; Office for National Statistics, 2026; Scotland’s Census, 2025) and HESA data (HESA, 2026b) will be used to update these predictions in the approaching years. Moreover, previous research on predicting the future representation of ethnic groups in the UK (Rees et al, 2011) suggests that the method for predicting an end to underrepresentation (Figure 2) can be refined.

Conclusion

There has been an increase in the percentage of the professoriate who are Black (Gibney, 2024). Nevertheless, there does not appear to have been a reduction in the underrepresentation of Black female professors or Black male professors between 2014–15 and 2024–25 (Figure 2). Despite this lack of reduction in underrepresentation, it is provisionally predicted that the underrepresentation of Black female professors and Black male professors will end in 2043–44 and 2037–38 respectively. However, the prediction for Black female professors seems unlikely given the plateauing indicated in the representation of Black female non-professors (Figure 3a). Hopefully, predictions will be strengthened through subsequent data and improved methodology; it is intended that this blog post encourages efforts to monitor and predict the underrepresentation of Black professors over time so that there can be a clear idea of where the situation is heading.

Box 1

Statistical Analysis: Underrepresentation

Data and analysis. Data of professors in UK higher education institutions for the 2024–25 academic year (HESA, nd-a), and UK Census data from 2021/2022 censuses (Office for National Statistics, 2025), were analysed. R Version 4.5.2 (R Core Team, 2025) was used to run z-tests – tests for seeing if there is a statistically significant underrepresentation – and to calculate Cohen’s h effect sizes (Cohen, 1988; Zieffler, 2025) – to signify the magnitude of the underrepresentation. A z-test found that, statistically, the representation of Black females is significantly lower in female professors than amongst females who are between 45 and 64 years of age (2(1) = 171.08, p < .001, Cohen’s h = .19). Likewise, a z-test demonstrated that Black males are significantly less represented amongst the male professoriate than they are amongst 45-to-64-year-old males (2(1) = 241.78, p < .001, Cohen’s h = .15). Cohen’s hs indicated that these underrepresentations are not negligible (see my first blog post). Caveats. Between 2021/2022 and 2024, there probably was a slight increase in the representation of Black females and males amongst 45-to-64-year-olds (Figure 2). So, comparing 2024–25 data of professors to 2021/2022 census data (as was done in the present blog) is likely to somewhat underestimate the underrepresentation. Probably, the number of individuals in HESA’s professor category does not reach up to the actual total of professors (HESA, nd-b). However, as discussed in my second blog post, the percentage of Black people in that category likely does well enough as a stand-in for the actual percentage of professors who are Black. It should be mentioned that whilst the proportion of professors who are female has risen, females nevertheless account for a minority of professors (Advance HE, 2024), with 32% being female in the 2024–25 academic year and the majority being male (HESA, 2026a) – in the current analysis, percentages were calculated separately for females and males.

Note. References: Advance HE (2024), Cohen (1988), HESA (nd-a, nd-b, 2026a), Office for National Statistics (2025), R Core Team (2025), Zieffler (2025), my first and second blog posts.

Box 2

Black Representation in 45-to-64-year-olds in the UK: 2011 and 2021/2022
Going by Figure 2, in the UK, Black representation in 54.5-year-olds seems to be in the ballpark of i) the estimated Black representation amongst 45-to-64-year-olds in 2011 and, ii) the percentage of 45-to-64-year-olds who are Black in 2021/2022. Percentages for 2021/2022 were calculated directly from census data. I estimated the percentages for 2011, and this estimation involved a few steps which are described next. 2011: England and Wales. Data are available for the 2011 Census for 45-to-64-year-olds in the population of England and Wales for females and males by ethnic background (Nomis, 2013). I used that data to calculate the percentage of 45-to-64-year-olds who are Black in 2011 for females (2.63%) and males (2.37%) in England and Wales. 2021/2022: UK, England and Wales. Using 2021/2022 Census data (Office for National Statistics, 2025), I divided the percentage of the UK 45-to-64-year-old population who are Black (3.75% for females, 3.44% for males) by the percentage of the England and Wales 45-to-64-year-old population who are Black (4.17% for females, 3.79% for males) for females and males separately. 2011: UK. Dividing the 2021/2022 UK percentage by the 2021/2022 England and Wales percentage gave a number (.90 for females and .91 for males) which I multiplied the 2011 England and Wales percentages by for females and males. Multiplying gave estimates of the percentage of 45-to-64-year-olds in the 2011 UK population who are Black – 2.36% for females and 2.15% for males.

Note. References: Nomis (2013), Office for National Statistics (2025).

References

Cohen, J. (1988). Statistical power analysis for the behavioral sciences (2nd ed.). Lawrence Erlbaum Associates.

Zarus Cenac has worked at UK universities, for example, he was a visiting lecturer at City, University of London. He is currently an administrator at UCL. His interests include race and ethnicity from an interdisciplinary perspective.


Leave a comment

The Doorknob and the Door(s): Why Bayes Matters Now

By Paul Alper

When I was young, there was a sort of funny story about someone who invented the doorknob but died young and poor because the door had yet to be invented. And, perhaps the imagery is backwards in that the door existed but was useless until the doorknob came into being but I will stick with the doorknob coming first in time. Bear with me as I attempt to show the relevance of this to the current meteoric rise of Bayesianism, a philosophy and concept several centuries old. 

In a previous posting, “Statistical Illogic: the fallacy of Jacob Bernoulli and others,” I reviewed the book, Bernoulli’s Fallacy by Aubrey Clayton.  He shows in great detail how easy it is to confuse what we really should want

Prob(Hypothesis| Evidence)                                       Bayesianism

with

Prob(Evidence | Hypothesis)                                       Frequentism

A classic instance of Bayesian revision in higher education would be the famous example at the Berkeley campus of the University of California. In the 1970s, it was alleged that there was discrimination against females applying to graduate school.  Indeed, male admission rate overall was higher than female admission rate.  But, according to https://www.refsmmat.com/posts/2016-05-08-simpsons-paradox-berkeley.html, the simple explanation

“is that women tended to apply to the departments that are the hardest to get into, and men tended to apply to departments that were easier to get into. (Humanities departments tended to have less research funding to support graduate students, while science and engineer departments were awash with money.) So women were rejected more than men. Presumably, the bias wasn’t at Berkeley but earlier in women’s education, when other biases led them to different fields of study than men.”

Clayton’s examples, such as the Prosecutor’s Fallacy and medical testing confusion, give no hint of how analytically difficult it was to perform the calculations of Bayes Theorem in complicated situations. Except for a paragraph or two on pages 297 and 298 he makes no reference to how and why Bayesianism calculations can now be done numerically on very complicated, important, real-life problems in physics, statistics, machine learning, and in many other fields, thus the proliferation of Bayesianism.

For the record, the one and only picture of the reverend Thomas Bayes is generally considered apocryphal; ditto regarding the one and only picture of Shakespeare.   Bayes died in 1761 and his eponymous theorem was presented to The Royal Society in 1763 by Richard Price, an interesting character on his own.

What has changed since the inception of Bayes Theorem more than two centuries ago, the door knob if you will, is the advent of the door: World War II and the computer. At Los Alamos, New Mexico, the place that gave us the atom bomb, five people were confronted with a complicated problem in physics and they came up with a numerical way of solving Bayes Theorem via an approach known as MCMC, which stands for Markov Chain Monte Carlo. Their particular numerical way of doing things is referred to as the “Metropolis Algorithm” named after Nicholas Metropolis, the individual whose name was alphabetically first.

To give the flavour but not the details of the Metropolis algorithm, I will use a well-done, simple example I found on the web which does not use or need the Metropolis algorithm but can be solved simply using straightforward Bayes Theorem; then I show an inferior numerical technique before indicating how Metropolis would do it. The simple illustrative example is taken from the excellent web video, Bayes theorem, the geometry of changing beliefs (which in turn is taken from work by Nobel prize-winning psychologists Daniel Kahneman and Amos Tversky).

The example starts with ‘Steve’, a shy retiring individual. We are asked to say which is more likely – that he is a librarian, or a farmer? Many people will say ‘librarian’, but that is to ignore how many librarians and how many farmers there are in the general population. The example suggests there are 20 times as many farmers as librarians, so we start with 10 librarians and 200 farmers and no one else.  Consequently,

Prob(Librarian) is 10/(10 +200) = 1/21.

Prob(Farmer) is 200/(10 +200) = 20/21

The video has 4 of the 10 Librarians being shy and 20 of the 200 farmers being shy; a calculation shows how the evidence revises our thinking:

Prob(Librarian| shyness) = 4/(4+20) = 4/24 = 1/6

Prob(Farmer| shyness) = 20/(4+20) = 5/6

‘Steve’ is NOT more likely to be a librarian. The probability that ‘Steve’ is a librarian is actually one in six. Bayesian revision has been calculated and note that the results are normalised.  That is, the 5 to 1 ratio, 20/4, trivially leads to 5/6 and 1/6.  Normalisation is important in order to calculate mean, variance, etc. In more complicated scenarios in many dimensions normalisation remains vital but difficult to obtain.

The problem of normalisation can be solved numerically but not yet in the Metropolis way.  Picture a 24-sided die.  At each roll of the die, record whether the side that comes up is a number 1,2,3 or 4 and call it Librarian. If any other number, 5 to 24, comes up, call it Farmer.  Do this (very) many thousands of times and roughly 1/6 of those tosses will be librarian and 5/6 will be farmer.  This sampling procedure is deemed independent in that a given current toss of the die does not depend on what tosses took place before.  Unfortunately, this straight-forward independent sampling procedure does not work well on more involved problems in higher dimensions.

Metropolis does a specific dependent sampling procedure, in which the choice of where to go next does depend on where you are now but not how you got there, ie  the previous places you visited play no role.  Such a situation is called a Markov process, a concept which  dates from the early 20th century. If we know how to transition from one state to another, we typically seek the long-run probability of being in that state. In the Librarian/Farmer problem, there are only two states, Librarian and Farmer. The Metropolis algorithm says begin in one of the states, Librarian or Farmer, toss a two-sided die which proposes a move.  Accept this move as long as  you do not go down. So, moving from Librarian to Librarian, Farmer to Farmer or Librarian to Farmer are accepted. Moving from Farmer to Librarian may be accepted or not; the choice depends on the relative heights – the bigger the drop, the less likely the move is to be accepted.  Metropolis says: take the ratio, 4/20, and compare to a random number between zero and one. If the random number is less than 4/20, move from Farmer to Librarian; if not, stay at Farmer. Repeat the procedure (very) many, many times.

Typically, there is a burn-in period so the first bunch are ignored and we count from then on the fraction of the runs that we are in the Librarian state or in the Farmer state, to yield the 1/6 and 5/6.

Multiple thousands of iterations today take no time at all; back in World War II, computing was in its infancy and one wonders how many weeks it took to get a run which today, would be done in seconds.  But, so to speak, a door was being constructed. 

In 1970, Hastings introduced an additional term so that for complex cases, the proposals and acceptances would better capture more complex, involved “terrain” than this simple example. In keeping with the doorknob and door imagery, Metropolis Hastings is a better door, allowing us to visit more complicated, elaborate terrain more assuredly and more quickly.  An even newer door, inspired by problems in physics, is known as the  Hamiltonian MCMC.  It is even more complicated, but it is still a door,related to previous MCMC doors.  There are many web sites and videos attempting to explain the details of these algorithms but it is not easy going to follow the logic of every step.  Suffice to say, however, the impact  is enormous and justifies the resurgence of Bayesianism.

Paul Alper is an emeritus professor at the University of St. Thomas, having retired in 1998. For several decades, he regularly contributed Notes from North America to Higher Education Review. He is almost the exact age of Woody Allen and the Dalai Lama and thus, was fortunate to be too young for some wars and too old for other ones. In the 1990s, he was awarded a Nike sneaker endorsement which resulted in his paper, Imposing Views, Imposing Shoes: A Statistician as a Sole Model; it can be found at The American Statistician, August 1995, Vol 49, No. 3, pages 317 to 319.


Leave a comment

Statistical illogic: the fallacy of Jacob Bernoulli and others

by Paul Alper

Bernoulli’s Fallacy, Statistical Illogic and the Crisis of Modern Science by Aubrey Clayton.  

“My goal with this book is not to broker a peace treaty; my goal is to win the war.”    (Preface p xv)

“We should no more be teaching p-values in statistics courses than we should be teaching phrenology in medical schools.” (p239)

It is possible or even probable that many a PhD or journal article in the softer sciences has got by through misunderstanding probability and statistics. Clayton’s book aims to expose the shortcomings of a fallacy first attributed to the 17th century mathematician Jacob Bernoulli, but relied on repeatedly for centuries afterwards, despite the 18th century work of statistician Thomas Bayes, and exemplified in the work of RA Fisher, the staple of so many social science primers on probability and statistics.

In the midst of the frightening Cold War, I attended a special lecture at the University of Wisconsin-Madison on 12 February 1960 by Fisher, the most prominent statistician of the 20th century; he was touring the United States and other countries. I had never heard of him and indeed, despite being in grad school, my undergraduate experience was entirely deterministic: apply a voltage then measure a current, apply a force then measure acceleration, etc. Not a hint, not a mention of variability, noise, or random disturbance. The general public’s common currency in 1960 did not then include such terms as random sample, statistical significance, and margin of error. 

However, Fisher was speaking on the hot topic of that day: was smoking a cause of cancer?  Younger readers may wonder how in the world was this a debatable subject when in hindsight, it is so strikingly obvious. Well, it was not obvious in 1960 and the history of inflight smoking indicates how difficult it was to turn the tide, and how many years it took. Fisher’s tour of the United States was sponsored by the tobacco industry, but it would be wrong to conjecture that he was being hypocritical. And not just because he was a smoker himself.  

Fisher believed that mere observations were insufficient for concluding that A causes B; it could be that B causes A or that C is responsible for both A and B. He insisted upon experimental and not mere observational evidence. According to Fisher, it could be that people who have some underlying physical problem led them to smoke rather than smoking caused the underlying problem; or that some other cause such as pollution was to blame. According to Fisher, in order to experimentally link smoking as the cause of cancer, at random some children would be required to smoke and some would be required not to smoke and then as time goes by note the incidence of cancer in each of the two groups.

However, according to Clayton, Fisher himself, just like Jacob Bernoulli, had it backwards when it came to analysing experiments.  If Fisher and Bernoulli can make this mistake, it is easy for others to fall into this trap because ordinary language keeps tripping us up.  Clayton expends much effort into showing examples, such as the famous Prosecutor’s Fallacy. The fallacy was exemplified in the UK by the infamous Meadows case and is discussed at length by Clayton; a prosecution expert witness made unsustainable assertions about the probability of innocence being “one in 73 million”.

The Bayesian way of looking at things is to consider the probability a person is guilty, given the evidence. This is not the same as the probability of the evidence, given the person is guilty, which is the ‘frequentist’ approach adopted by Fisher, with results which can be wildly different numerically. Another example, from the medical world: there is confusion between the probability of having a disease, given a positive test for the disease:

                        Prob (Disease | Test Positive) ; the Bayesian way of looking at things

and

                         Prob (Test Positive | Disease) ; the frequentist approach

The patient is interested in the former but is often quoted the latter, known as the sensitivity of the test, which might be markedly different depending on the base rate of the disease. If the base rate is, say, one in 1,000 and the test sensitivity is, say, 90%, then for every 1000 tests, 100 will be false positives. A Bayesian would therefore conclude correctly that the chances of a false positive test are 100 times greater than the chances of actually having the disease. In other words, the hypothesis that the person has the disease is not supported by the data/evidence. However a frequentist might mistakenly say that if you test positive there is a 90% chance that you have the disease.

The quotation from page xv of Clayton’s preface which begins this essay, shows how much Clayton, a Bayesian, is determined to counter Bernoulli’s fallacy and set things straight. Fisher’s frequentist approach still finds favor among social scientists because his setup, no matter how flawed, was an easy recipe to follow. Assume a straw-man hypothesis such as ‘no effect’, take data to obtain a so-called p-value and, in the mechanical manner suggested by Fisher, if the p-value is low enough, reject the straw man. Therefore, the winner was the opposite of the straw man, namely the effect/hypothesis/contention/claim is real.

Fisher, a founder, and not just a follower of the eugenics movement, was as I once wrote, “a genius, and difficult to get along with.”  Upon reflection, I consequently changed the conjunction to an implication, “a genius, therefore difficult to get along with.”  His then son-in-law back on 12 February 1960 was George Box, also a famous statistician – among other things the author of the famous phrase in statistics, “all models are wrong, some are useful” – who had just been appointed to be the head of the University of Wisconsin’s statistics department. Unlike Fisher, Box was a very agreeable and kindly person and, as evidence of those qualities, I note that he was on the committee that approved my PhD thesis, a writing endeavour of mine which I hope is never unearthed for future public consumption.  

All of that was a long time ago, well before the Soviet Union collapsed, only to see today’s military rise of Russia. Tobacco use and sales throughout the world are much reduced while cannabis acceptance is on the rise. Statisticians have since moved on to consider and solve much weightier computational problems via the rubric of so-called Data Science. I was in my mid-twenties and I doubt that there were many people younger than I was at that Fisher presentation, so I am on track to be the last one alive who heard a lecture by Fisher disputing smoking as a cause of cancer.  He died in Australia in 1962, a month after my 26th birthday but his legacy, reputation and contribution live on and hence, the fallacy of Bernoulli as well.    

Paul Alper is an emeritus professor at the University of St. Thomas, having retired in 1998. For several decades, he regularly contributed Notes from North America to Higher Education Review. He is almost the exact age of Woody Allen and the Dalai Lama and thus, was fortunate to be too young for some wars and too old for other ones. In the 1990s, he was awarded a Nike sneaker endorsement which resulted in his paper, Imposing Views, Imposing Shoes: A Statistician as a Sole Model; it can be found at The American Statistician, August 1995, Vol 49, No. 3, pages 317 to 319.